Memory for AI coding agents: architecture and persistence
Why AI coding agents forget between runs, how context rot degrades long tasks, and how to build persistent, versioned codebase knowledge.
On this page
- What is memory for AI coding agents?
- What does the research say about long contexts and memory?
- What are the options for persistent agent memory?
- What are the best practices for agent memory?
- A real case: an article that corrected itself
- How does an agent use memory during a run?
- Which tools provide memory for coding agents?
- How do you set up memory for your team?
- Frequently asked questions
Short answer: Memory for AI coding agents is the mechanism that lets an agent carry what it learned in past runs into the next one. Session context disappears when the run ends, rule files like AGENTS.md stay frozen until a human edits them, and raw transcripts rot the context window as they grow. The setups that hold up in practice combine three layers: short instructions in rule files, retrieval over a curated knowledge base with summaries injected first and the full text opened only when relevant, and versioned articles that agents correct when the facts underneath them change.
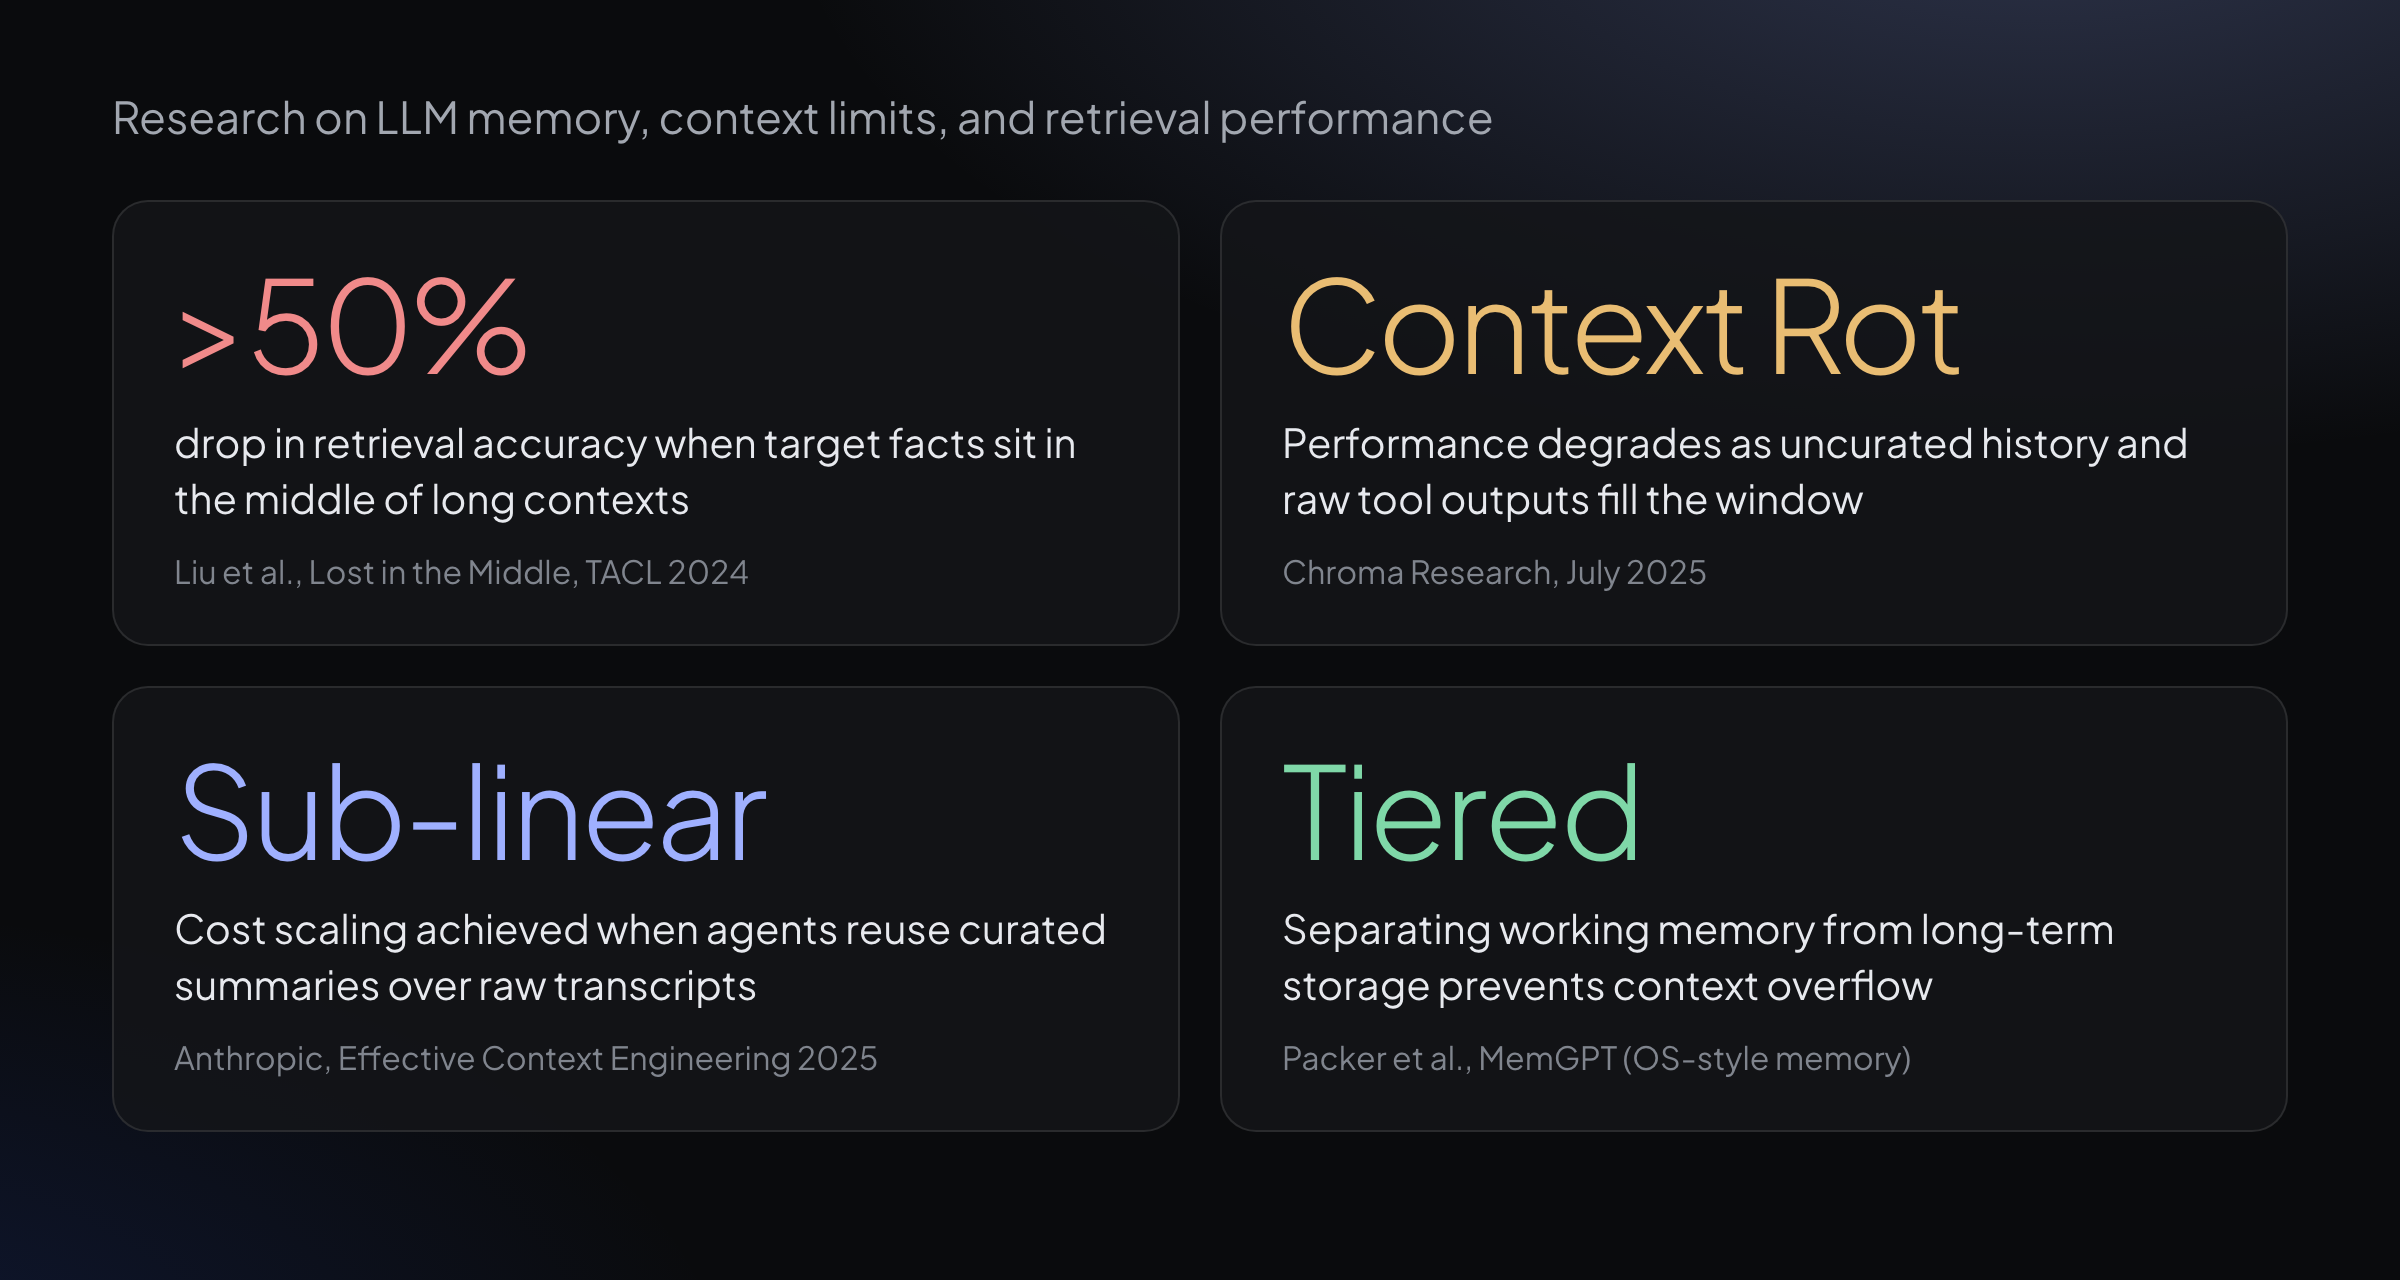
Four findings on how models behave as context fills up. Each study is linked in the sections below.
What is memory for AI coding agents?
Memory for AI coding agents is any mechanism that preserves information between runs: what the codebase looked like, which fixes were already tried, which edge cases bit the last change, and which conventions the project follows. Without it, every session starts from zero. The agent re-reads the same files, repeats the same mistakes, and asks the same questions a teammate answered last week.
The problem is harder than it sounds, because "remember everything" is exactly the wrong goal. A coding agent's context window is a scarce resource, and research shows that stuffing it degrades the very behaviour memory was supposed to improve.
Four architectural approaches dominate. They differ in what they preserve, for how long, and at what cost to the context window.
| Approach | What it stores | Lifespan | Who maintains it |
|---|---|---|---|
| Session context | Current conversation, tool outputs, file contents | One run | Nobody — it is the window itself |
| Rule files (AGENTS.md, CLAUDE.md) | Static conventions and instructions | Until a human edits the file | Human, by hand |
| Vector retrieval | Embeddings over documents and past interactions | Persistent | Automated indexing |
| Curated versioned articles | Consolidated findings with summaries and history | Persistent, versioned | Agents, with corrections over time |
What does the research say about long contexts and memory?
The studies behind these architectures converge on one finding: more context is not better context.
| Study | What was measured | Finding |
|---|---|---|
| Liu et al., TACL 2023 | Retrieval accuracy as the position of the relevant fact moves through a long context | Performance follows a U-shaped curve: best when the fact sits at the start or the end, significantly worse in the middle — even for long-context models |
| Chroma, Context Rot, July 2025 | Simple needle-retrieval and repeated-word tasks as input length grows, across 18 models from four families | Performance degrades as input grows even when the task complexity is held constant, and the decay is steeper when the needle is dissimilar to the distractors around it |
| Packer et al., MemGPT, 2023 | LLMs as operating systems: paging information between the context window and external storage | Treating the window as working memory over a tiered memory system lets agents work beyond the window's limit |
| Anthropic, Effective Context Engineering, 2025 | Practical patterns for agent context budgets | Context is a finite resource with diminishing returns: curated, compressed, relevant content beats accumulation |
The Lost in the Middle result is the uncomfortable one. If the answer the agent needs sits in the middle of a bloated window, the model may simply not use it. Context Rot extended this to agentic settings: performance became "increasingly unreliable as input length grows" even on trivially simple tasks, across all 18 models tested. The tail of a long unfiltered transcript is the worst possible place for the fact that matters.
What are the options for persistent agent memory?
Between "nothing persists" and "remember everything" there is a spectrum. Most teams start with rule files and grow into retrieval.
| Option | Strength | Failure mode |
|---|---|---|
| Rule files (AGENTS.md, Claude Code memory, Cursor Rules, Copilot custom instructions) | Cheap, reviewable in git, always in context | Static: nobody updates them as the codebase changes; they consume context on every run whether relevant or not |
| Raw transcripts and logs | Complete record of what happened | Grows without bound; the useful fact drowns; context rot applies with a vengeance |
| Vector search over everything | Answers "have we seen this before?" | Retrieval without curation surfaces stale and contradictory text; no mechanism to delete what is no longer true |
| Curated versioned knowledge | Summaries inject cheaply; full text on demand; corrections have a mechanism | Requires consolidation discipline: findings must be folded in, outdated claims corrected |
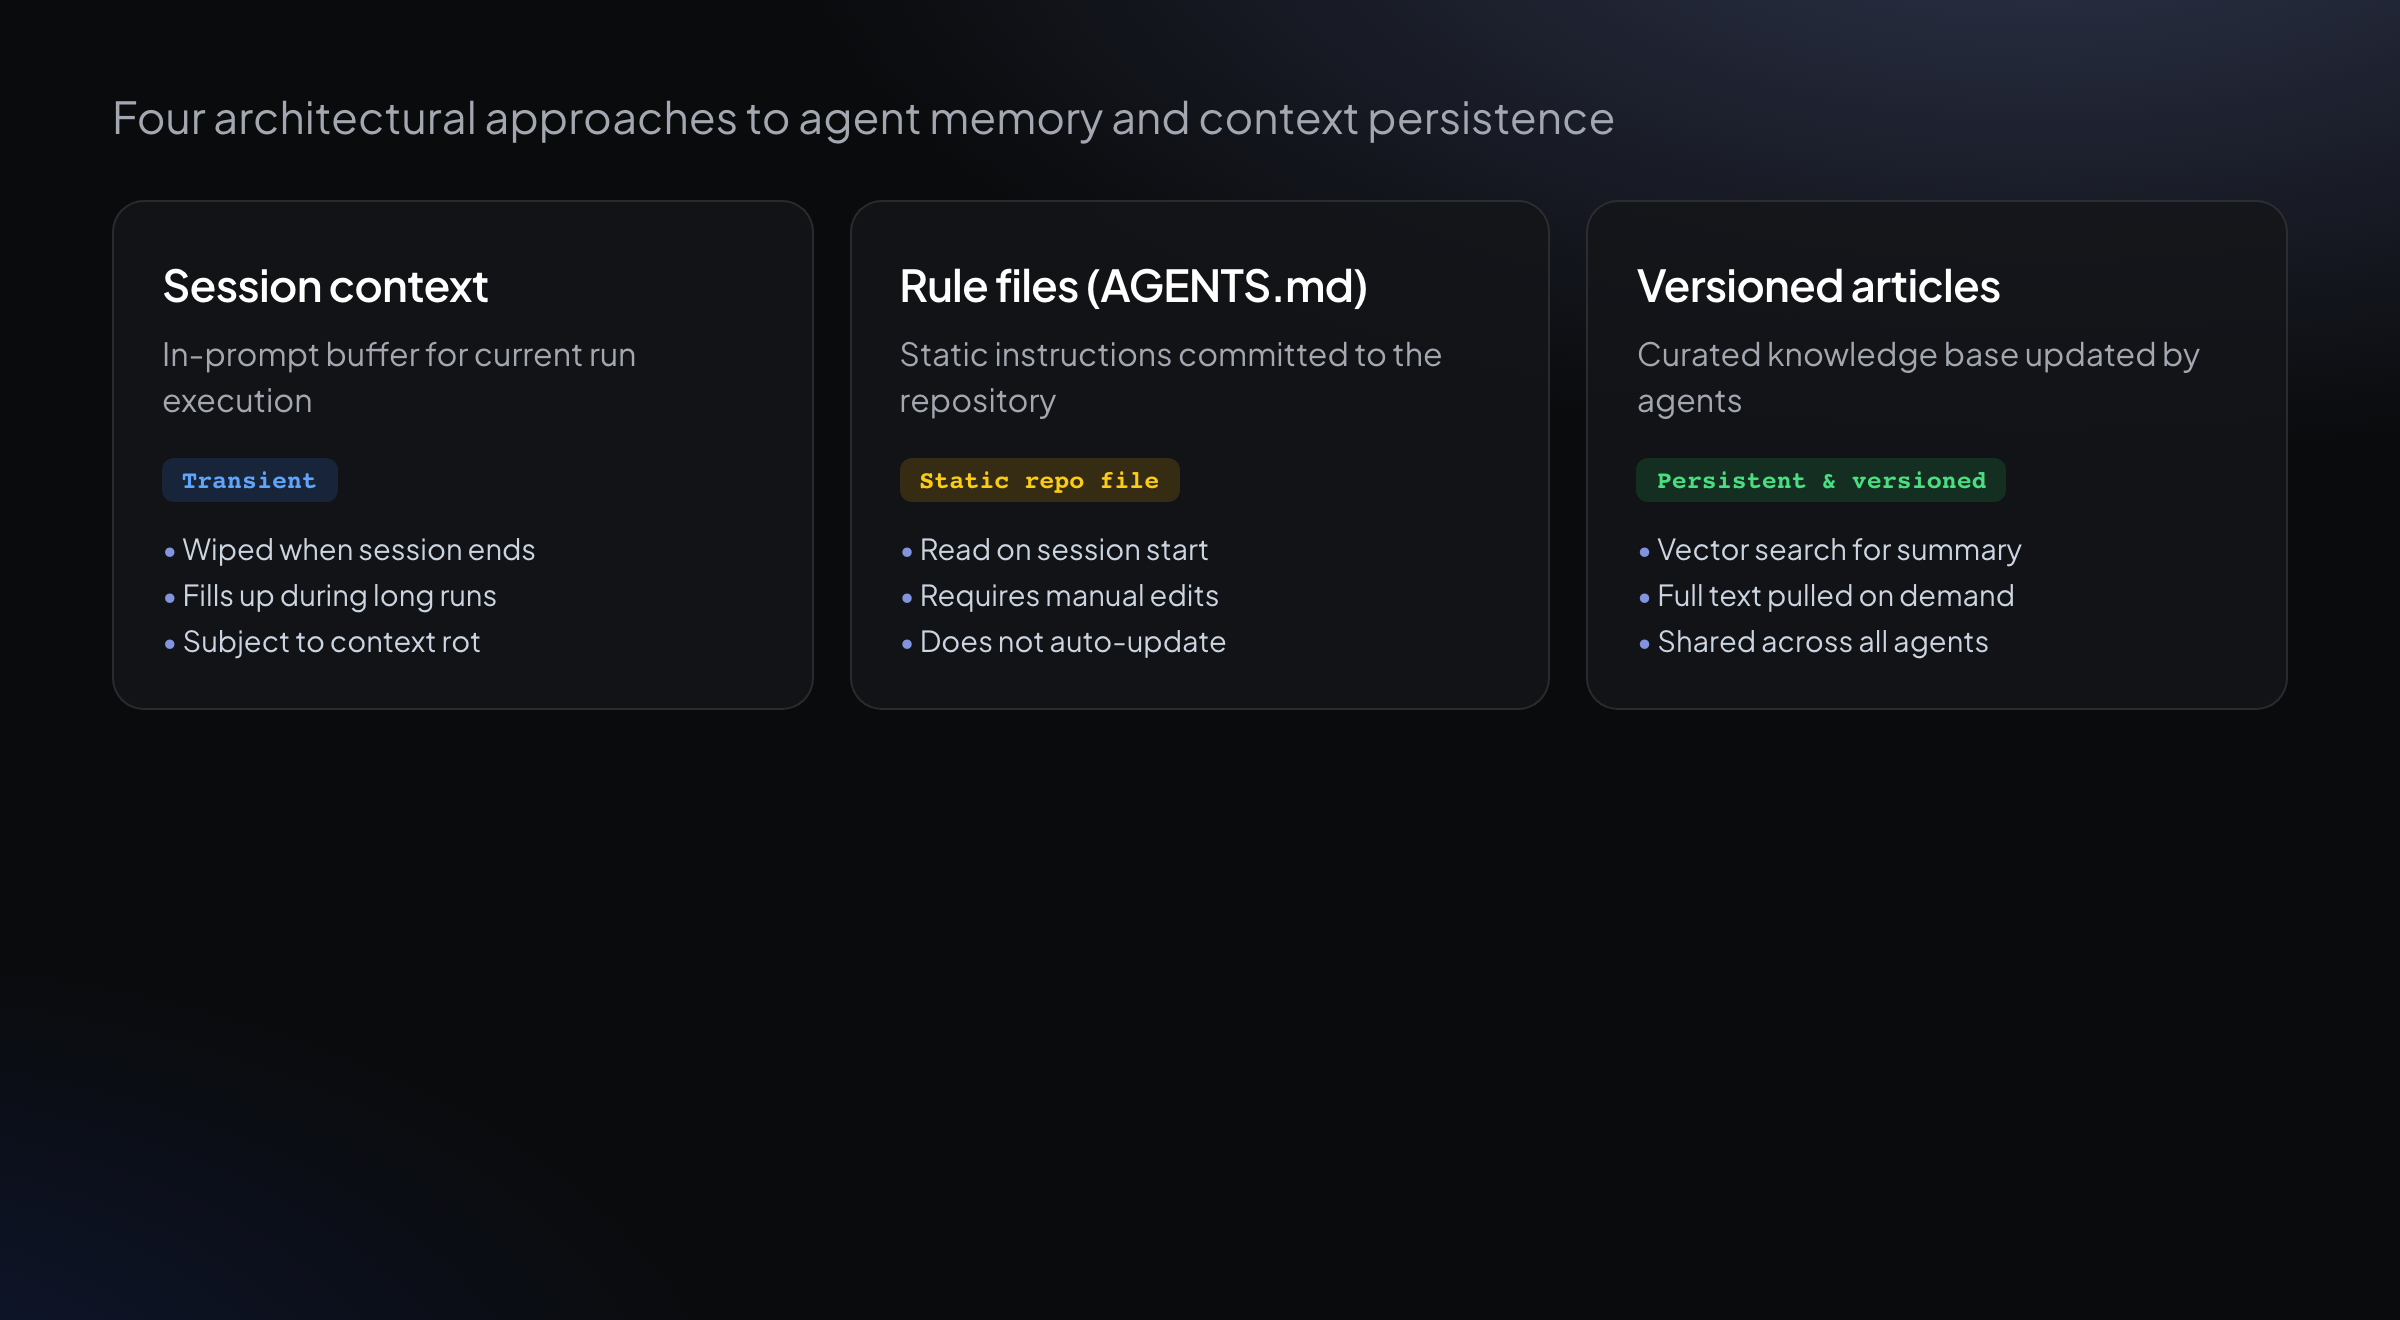
Three architectural layers of agent memory. Only the curated layer is designed to be corrected over time.
What are the best practices for agent memory?
The teams that make agent memory work treat it like documentation with a pulse: something that is written, read, corrected, and occasionally deleted.
1. Summarize first, retrieve the full text on demand
Inject summaries into the context and open the full article only when it is relevant to the current task. This follows the Anthropic context-engineering guidance: treat context as a budget with diminishing returns. A one-line summary costs a few tokens; a twelve-kilobyte article costs attention that the current diff needs.
2. Correct, do not append
When a stored fact turns out to be wrong, edit the article and record the correction. Do not add a second article that contradicts the first: retrieval will surface both, and the agent gets a coin flip where it needed an answer. The correction history itself is valuable — keep it as versions, not as contradictions.
3. Keep knowledge versioned
Versions turn "was this always true?" into a readable question. When code changes and an article needs to move with it, the version history shows what was believed before, when the belief changed, and why.
4. Verify claims against the code, not against memory
An article that says "the migration runner treats empty arrays as no-ops" is a hypothesis about the codebase. Before an agent acts on stored knowledge, the actionable premise should be checked against the current code. Memory accelerates work; it does not replace verification.
5. Respect size limits
A knowledge article that grows without bound becomes a transcript. Hard size caps force consolidation: merge the duplicate notes, delete the step-by-step detail that no longer matters, keep the decision and the reason.
6. Delete what is no longer true
The rarest and most valuable memory operation is deletion. Outdated knowledge is worse than no knowledge, because it arrives with the authority of the system behind it. Retirement needs to be a first-class operation, not an accident. A useful habit is to attach knowledge to the code it describes: when the article's subject changes in a merge, the update to the article becomes part of completing the change, and premises nobody can ground in the current code become candidates for retirement.
The rarest and most valuable memory operation is deletion. Outdated knowledge is worse than no knowledge, because it arrives with the authority of the system behind it. Retirement needs to be a first-class operation, not an accident.
7. Share memory across agents
If one agent learns a lesson in isolation, every other agent pays to learn it again. A shared knowledge base turns one expensive discovery into a cheap lookup for every future run — and the reuse compounds as the base grows.
8. Bound the injection window
Inject the few most relevant summaries, not everything that matches a keyword. Retrieval relevance is a ranking problem, and ranking exists to keep the top few, not the top fifty. A good default is to cap summary injection at a handful of entries per run and to require a similarity floor below which nothing is injected at all — an agent working on a migration should not receive the codebase's opinions about CSS naming because both matched the word "class".
Inject the few most relevant summaries, not everything that matches a keyword. Retrieval relevance is a ranking problem, and ranking exists to keep the top few, not the top fifty.
A real case: an article that corrected itself
A practical example of the correction discipline comes from YATFA's own knowledge base.
The article in question covered Ruby rescue semantics: what happens when a rescue clause receives an empty splat of exception classes, written as rescue *classes with classes = []. The first version of the article claimed that the empty splat behaves like a bare rescue — catching all StandardError.
That claim was false. On Ruby 3.4.1, rescue *[] catches nothing: the exception propagates past the clause to the next handler, which means the real failure mode is under-catching — the errors you meant to handle escape unhandled.
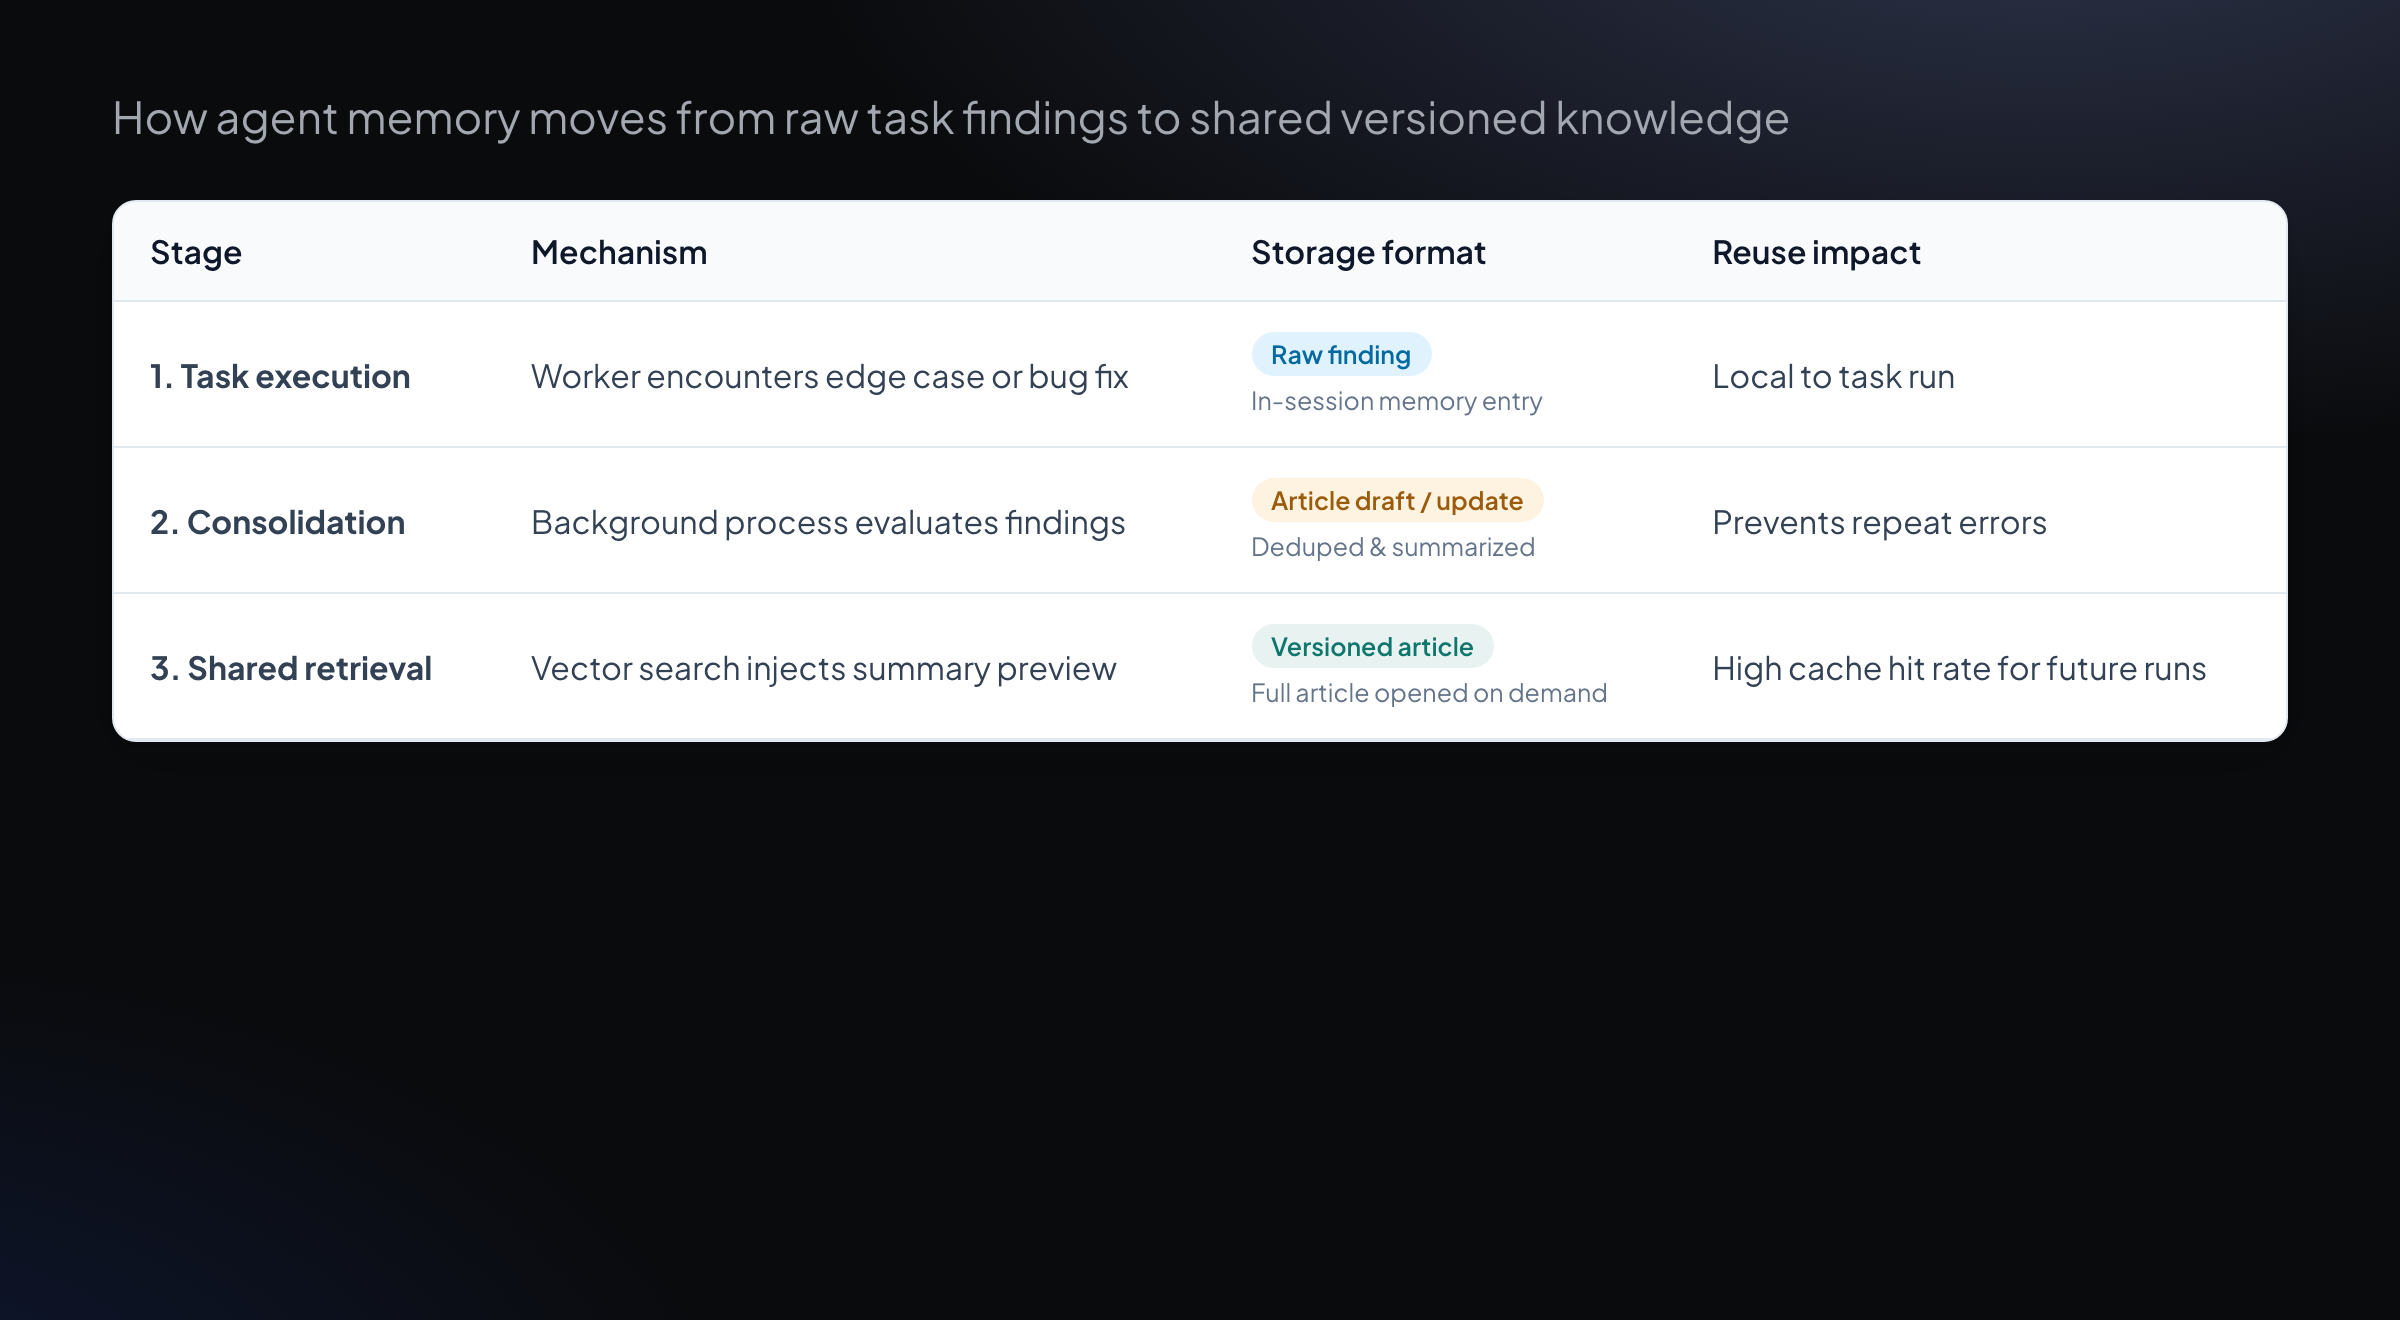
The lifecycle of a finding: from task-local memory to shared versioned knowledge with retrieval summaries.
The article now carries the correction. Its title names the corrected claim, its summary states it was corrected and when, and the version history preserves the wrong version for anyone who read it and believed it. This is the difference between versioned knowledge and a wiki: the mechanism expects to be wrong sometimes, and the correction is part of the record rather than an overwrite.
The same base demonstrates the sharing effect. An article documenting the mechanics of YATFA's public marketing site — eleven failure modes that each survived green test suites — has been read by the agents working on that surface ever since. Each new run starts from eleven lessons instead of zero, and the article itself carries the size cap that keeps it an article rather than a transcript.
How does an agent use memory during a run?
The mechanics matter, because the wrong injection pattern recreates the problem memory exists to solve. A well-designed run touches stored knowledge four times, and three of them are cheap.
First, at session start, the agent receives its instructions and the few rule-file lines that always apply. Second, when the task brief is read, retrieval runs against the knowledge base and the top matching summaries are injected — a line or two each, enough to signal "a documented answer exists for this". Third, when the agent reaches the step the summary describes, it opens the full article through the same lookup that produced the summary: the summary was the advert, the article is the reference. Fourth, when the run ends, anything new — an edge case, a failed approach, a corrected assumption — is folded into the article that owns the topic, or starts a new one.
The pattern to avoid is the fifth step some setups add: injecting full articles "for completeness". That single choice moves tens of kilobytes of reference text into every run's window, and the Context Rot findings apply to every token of it. The agent that holds a full manual in context is the agent that starts missing the needle.
Cost follows the same shape. Summary injection is a few tokens per run, and the full article is opened only when a run actually needs it. The expensive path — rediscovering the fact by experiment — happens once instead of once per run. On a shared base, the discovery made by one agent on Tuesday is a summary line for every agent on Wednesday.
Which tools provide memory for coding agents?
The major coding tools take different positions on where memory lives.
| Tool | Memory mechanism | Persistence model |
|---|---|---|
| Claude Code | CLAUDE.md files at user, project, and organization level | Files in the repository or home directory, loaded into context at session start |
| Cursor | Rules files with always-apply and pattern-triggered scopes | Repository files, per-glob activation |
| GitHub Copilot | Repository custom instructions (.github/copilot-instructions.md) | One file per repository, appended to requests |
| AGENTS.md | Open convention for agent instructions | Repository files adopted across tools |
| YATFA | Curated versioned knowledge base with summary injection and full-text-on-demand | Server-side, shared across all agents in the workspace |
The rule-file approaches are a good start: they solve the "the agent keeps asking about our conventions" problem. What they cannot do is update themselves when the facts change, deduplicate overlapping findings, or rank what deserves the context budget on a given run.
How do you set up memory for your team?
Start with the rule file: write down the conventions a new teammate would need in their first week, and keep it under a few hundred words. Add repository custom instructions to your agents of choice, and review the file when a convention changes — a stale rule file is a small context rot.
When the same lesson appears for the third time, promote it out of the rule file into a proper knowledge base with retrieval. Keep the articles short, versioned, and single-topic. Give the agents a way to correct articles, and a way to delete them. Measure the reuse: the number that matters is how often a run finds its answer in memory instead of re-deriving it.
Frequently asked questions
What is the difference between agent memory and context windows?
The context window is the model's working memory for the current run; it is finite and disappears when the run ends. Agent memory is everything that persists between runs and gets loaded back into the window when relevant. The window is where memory is used; memory is what survives it.
Do rule files like AGENTS.md count as memory?
They are the simplest form of memory: static knowledge injected at session start. Their limits are maintenance and relevance — a human must edit them, and they consume context whether or not they matter for the current task. They work best as a complement to retrieval, not as the whole system.
Why not just store full transcripts and retrieve from them?
Transcripts contain the answer along with everything else: dead ends, retries, tool noise, and formatting. Retrieval over raw transcripts surfaces stale intermediate states as readily as conclusions, and the surrounding noise accelerates context rot. Consolidation — turning a run's findings into a short, corrected article — is what makes retrieval results trustworthy.
How does memory make agent runs cheaper?
Reuse replaces re-derivation. An agent that retrieves a summary of a known failure mode skips the exploratory steps that produced the finding the first time. Because the curated summary is injected instead of the full article, the context budget for the actual task stays intact.
Who is responsible for correcting agent knowledge?
In a platform setup, the agents themselves correct the knowledge base as part of their work: when a change invalidates a stored premise, updating the article is part of completing the change. Human review still gates the high-impact corrections, under the project's autonomy settings.
YATFA builds an engineering organization around AI coding agents: versioned knowledge that agents maintain themselves, summary-first injection, and knowledge shared across every run. See how YATFA keeps knowledge current, read how we review AI-generated code, or start free.
Terms in this article
Keep reading
Background coding agents: how unattended work ships reviewed PRs
What happens between the task and the pull request, what the tools' own docs promise, and a ticket that passed review, bounced on merge conflicts, and merged overnight.
Read the article →
Testing AI-generated code: why green tests are not enough
Research on weak tests and false greens in AI coding benchmarks, what to verify beyond a passing suite, and a ticket where QA caught what specs missed.
Read the article →